
Metadata tagging is the practice of attaching creative asset metadata, structured descriptive information about your assets, so that a photo, logo, or video can be found by what it is and what it is for, rather than by the name someone happened to give the file. The name of the game is retrieval: if a teammate can locate the current approved logo in a few seconds without asking anyone, your tagging works. If they scroll through folders named "final_v2" hoping for the best, it does not.
Most guides on this topic either stay abstract or jump straight to buying software. This one covers both sides: the metadata model you should set up regardless of tool, and what AI tagging can and cannot do for a creative team, because the SERP for this topic is dominated by DAM vendors for a reason. Tagging is the feature that most reliably separates a digital asset management system from a folder structure.
Tags vs. Metadata: The Difference That Matters
The two words get used interchangeably, but they behave differently in a library.
Metadata is structured information with a defined shape. A date taken, a camera model, a usage rights field, an approval status. A field has a defined type and a bounded set of values: one approval status, one expiry date, a fixed list of rights, which is what makes metadata filterable and reliable at scale. When a field says "Approved", that is a statement about the asset, not an opinion.
Tags are free-form labels. An asset can carry many tags, tags can be added by anyone, and they excel at description: "blue background", "outdoors", "team photo", "spring campaign". Their weakness is the mirror of their strength. When everyone invents their own labels, you end up with "holiday", "xmas", "Christmas_2025", and "festive" all pointing at the same photo and none of them finding it together.
The working rule used by most teams that tag well: tags describe content, fields govern process. What an asset looks like belongs in tags. What an asset is for, who approved it, when it expires, and what rights attach to it belongs in structured fields. If you are new to the wider discipline this sits inside, start with what digital asset management actually covers and how a DAM differs from plain file sharing.
The Four Kinds of Metadata Worth Managing
Not every metadata type deserves a place in your workflow. These four earn their keep.
1. Descriptive tags. What the asset shows and what it is called in your team's vocabulary. This is where AI tagging contributes the most, and where a small controlled vocabulary prevents chaos. Most teams do fine with 30 to 100 approved tags; beyond that, people guess and the guesses rot the index.
2. Technical metadata. EXIF data the file carries on its own: camera make and model, lens, ISO, date taken. You do not maintain this, you inherit it, and it is surprisingly useful. Filtering by camera body to pull every shot from a specific photoshoot, or by date taken rather than upload date to find event photos, saves minutes every single time. There is a reason file sharing tools cannot filter on this: a folder has no idea what EXIF is.
3. Rights and expiry metadata. Who owns it, where it may be used, and when it stops being usable. A license-restricted photo with no expiry field attached is a lawsuit with a nice thumbnail. Even a simple text field beats nothing, and a date field that someone actually checks beats a text field.
4. Workflow metadata. Approval status, campaign, client, version notes. These are custom fields you define, and they are what turns a library from an archive into a working system: a single-select "Approval Status" field with Draft, In Review, Approved, and Rejected gives you a Kanban view of your whole review queue. This is the same discipline that underpins creative workflow management, applied to the assets rather than the tasks.
Manual Tagging, AI Tagging, and Where Each One Fits
Manual tagging is not a failure state and AI tagging is not a replacement for it. They solve different problems.
Manual tagging is precise and slow. It is right for the metadata that carries authority: approval status, usage rights, the campaign an asset belongs to. A human should decide and record these, because they are statements your team will act on.
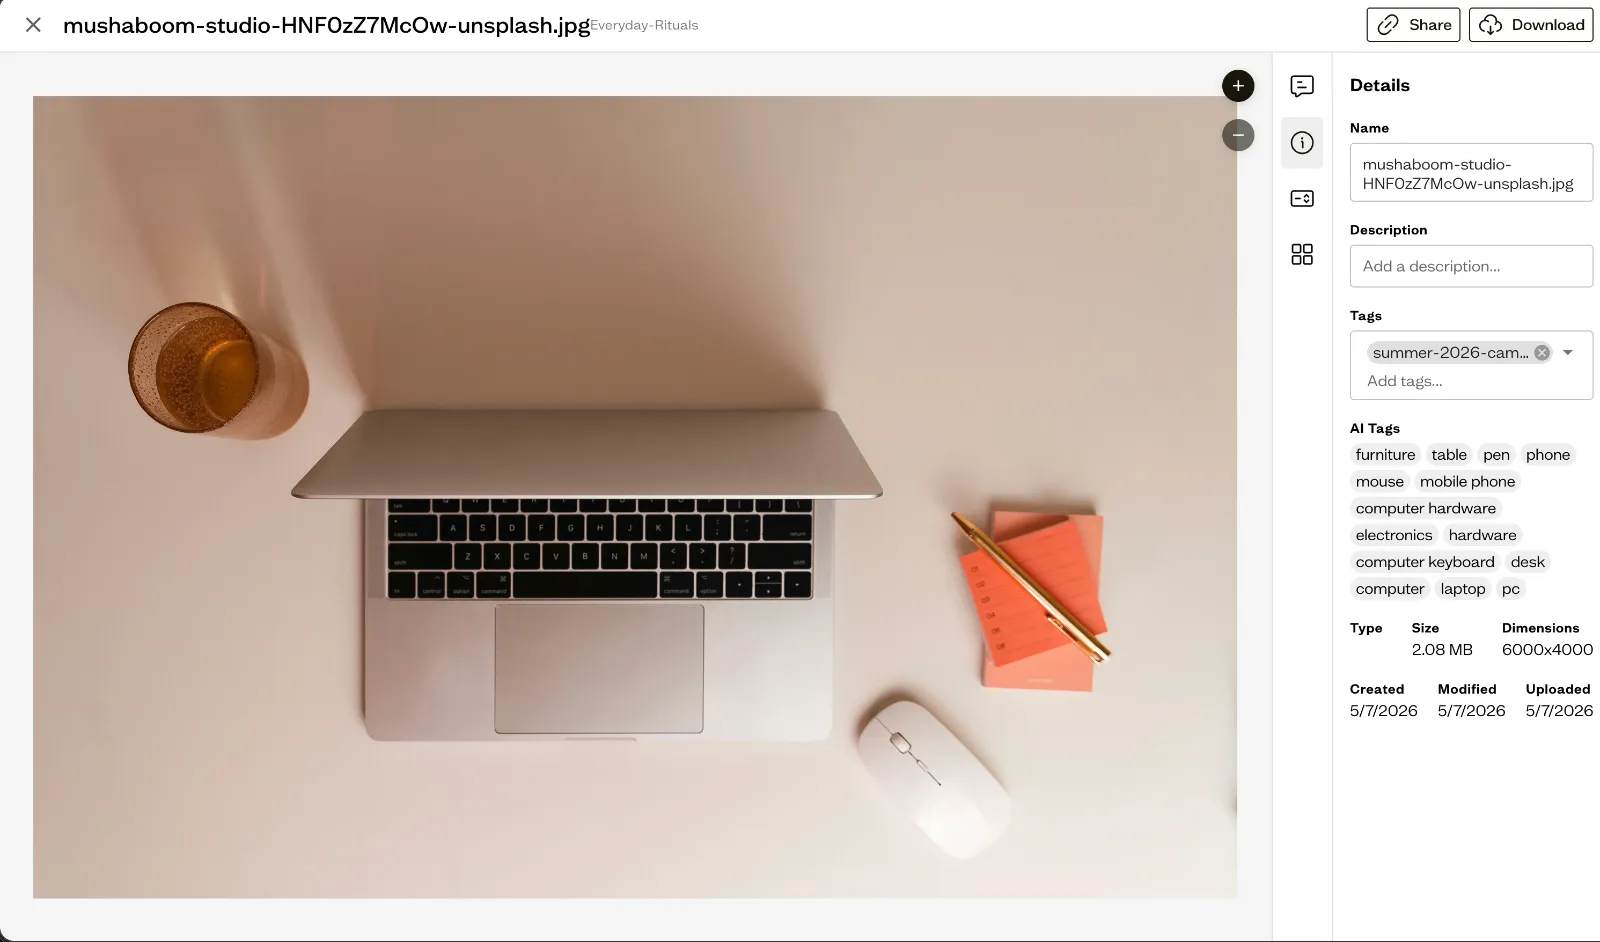
AI tagging is broad and instant. AI photo tagging happens at upload: the system recognizes objects, scenes, and colors, and tags the file automatically. Search "blue background" and get results nobody manually tagged for. This is what removes the backlog problem: the reason most tagging initiatives die is that nobody has time to tag 4,000 photos from the last three shoots, and auto tagging makes that backlog disappear at upload time.
AI visual search closes the loop from the other end. Instead of describing what you want in words, you pick an image that looks right and the system returns visually similar assets. For photography-heavy libraries this often beats keyword search outright, because "the one with the warm light and the wooden table" is a picture in your head, not a phrase.
The honest limits of AI tagging, which vendor pages tend to skip: AI is excellent at content and blind to context. It will tag "woman, laptop, office, smiling" and never know that she is the founder of your biggest client, that the photo is approved for internal use only, or that it is the hero image from last year's rebrand. Descriptive AI tags plus human-maintained structured fields is the combination that actually works.
Metadata Tagging Best Practices
These are the rules that survive contact with a busy team.
Keep the vocabulary small and enforced. A controlled tag list of a few dozen terms beats an open field everyone invents into. Review the list quarterly, merge synonyms, and delete tags that describe one campaign and will never apply again.
Be consistent, not clever. Decide once whether your client is "Acme" or "Acme Corp" and whether years in tags are "2025" or "25". Every inconsistency is a search that silently misses.
Unique, but not too specific. A tag that applies to one asset is a filename with extra steps. Tags earn their keep in aggregate: they should return groups, not singles.
Bulk operations or nothing. Tagging one asset at a time does not scale past the first month. Bulk tagging hundreds of assets in one pass, and bulk-updating a custom field across a selection, is the difference between a maintained library and an abandoned one.
Make the metadata visible. If tags and fields are only visible in an admin panel, people stop trusting them. A table view where columns are metadata fields lets the team see and sanity-check the data as part of normal work.
Tag for retrieval, not for storage. The test for any tag or field is not "is this true", it is "will someone search for this in six months". If nobody will ever filter on it, do not maintain it.
Retire metadata with the asset. Superseded assets should keep their tags but lose their discoverability, via an explicit status or an archive location. Otherwise your search results become a museum where the outdated logo outranks the current one.
Where Baseline Fits
Baseline handles this split natively. AI tagging runs automatically on upload and covers the descriptive layer: objects, colors, scenes, visual similarity search for finding images that look alike. The structured layer is yours to define: custom fields in single-select, multi-select, text, and date types for approval status, campaign, client, or usage rights, bulk-tagging for hundreds of assets at once, and table view to read the metadata like a spreadsheet. Technical metadata comes along for the ride, with EXIF filtering by camera make and model, and date-taken filtering separate from upload date.
The payoff is the search time. Baseline's own benchmark puts the saving from automated tagging and search at around 5 hours per person per week on asset hunting, which is the quiet tax that untagged libraries charge forever. Teams that pair this with a brand asset management framework feel it first, because every client library becomes searchable the day it is created.
Frequently Asked Questions
What is metadata tagging?
Attaching structured descriptive information, tags and fields, to assets so they can be found by content and purpose rather than filename. In practice it combines free-form descriptive tags, technical metadata like EXIF data, and structured custom fields for things like approval status and usage rights.
What is the difference between tagging and metadata?
Metadata is structured and usually single-valued: one approval status, one expiry date, one camera model (multi-select fields are the exception). Tags are free-form and multiple: as many descriptive labels as the asset warrants. Fields govern process; tags describe content. Libraries that blur the two end up with approval statuses nobody trusts.
Does AI tagging replace manual tagging?
No. AI tagging covers descriptive content automatically at upload time and clears the tagging backlog, but it cannot judge context: who the subject is, what rights attach, whether the asset is approved. AI tags for content, humans maintain the fields that carry authority.
How many tags should an asset have?
Enough to be found from several directions, which is usually three to eight descriptive tags plus its structured fields. Chasing exhaustive coverage burns the maintainer's goodwill and adds tags nobody will ever search.
What is a controlled vocabulary?
A fixed, maintained list of approved tags. It prevents the "holiday / xmas / Christmas_2025" problem where synonyms fragment the same concept across different labels. Keep it small, publish it, and prune it quarterly.
How do I start tagging an existing library?
Retroactively tagging everything is where good intentions die. Start by bulk-tagging the assets people actually search for: current logos, recent campaign photography, approved collateral. Let AI tagging cover new uploads, and backfill the archive in small batches when someone touches it anyway.
Metadata tagging is the least glamorous part of asset management and the part that pays back every day afterward. If you want to see how auto tagging, visual search, and custom fields work together, start a Baseline workspace for free.